Variance Vectors in Bundled Forecasts: Mathematical Approaches to Exposure Management When Combining Selections from Team, Equine, and Solo Events
Written by Kai Walter · Jun 7, 2026
Variance Vectors in Bundled Forecasts: Mathematical Approaches to Exposure Management When Combining Selections from Team, Equine, and Solo Events
Statistical analysts apply variance vectors to quantify directional risk when forecasters bundle selections from team events such as football matches, equine races, and solo competitions including tennis. These vectors extend traditional variance calculations by assigning directional components to each selection category, allowing exposure models to track how variability propagates through multi-leg structures. Data from aggregated forecast databases shows that covariance terms between categories often exceed 0.25 when outcomes share external factors like weather or scheduling constraints.
Defining Variance Vectors in Multi-Category Bundles
Researchers construct variance vectors as column matrices where each element corresponds to the standard deviation scaled by correlation coefficients derived from historical results across the three event types. Team event outcomes typically exhibit lower individual variances than equine selections yet higher cross-correlations with solo results during overlapping seasons. Observers note that the resulting vector norm provides a scalar exposure metric that forecasters use to adjust stake allocations before finalizing bundles.
Matrix decomposition techniques separate the total variance into orthogonal components aligned with each category. This decomposition reveals that equine selections frequently dominate the first principal component because of their higher outcome dispersion, whereas solo events contribute more to off-diagonal interactions. Studies published through academic channels indicate that reweighting these components reduces overall bundle variance by 12 to 18 percent in simulated portfolios drawn from five-year datasets.
Mathematical Frameworks for Exposure Calculation
Portfolio-style optimization adapts mean-variance methods by treating each bundled forecast as an asset whose return vector includes both expected probability margins and realized payout deviations. The exposure function incorporates a quadratic term that penalizes large positive eigenvalues in the category covariance matrix. Analysts solve the resulting constrained optimization using Lagrange multipliers, subject to minimum probability thresholds for each leg. This approach yields allocation weights that minimize the L2 norm of the aggregate variance vector while preserving target expected returns.
Monte Carlo simulations generate thousands of outcome paths by sampling from multivariate distributions fitted to past results in each category. Researchers calibrate the distributions using copula functions that capture tail dependencies observed during simultaneous high-stakes weekends. Output distributions then supply percentile-based exposure limits that operators apply to live bundles.
Integration Across Event Categories
Team selections introduce serial correlation structures tied to league schedules, while equine results depend on track conditions and field sizes. Solo events add volatility spikes around major tournaments. When combined, the full variance vector requires separate sub-matrices for intra-category and inter-category terms. Computational routines update these matrices daily using rolling windows of recent results, ensuring the model reflects current seasonal patterns.
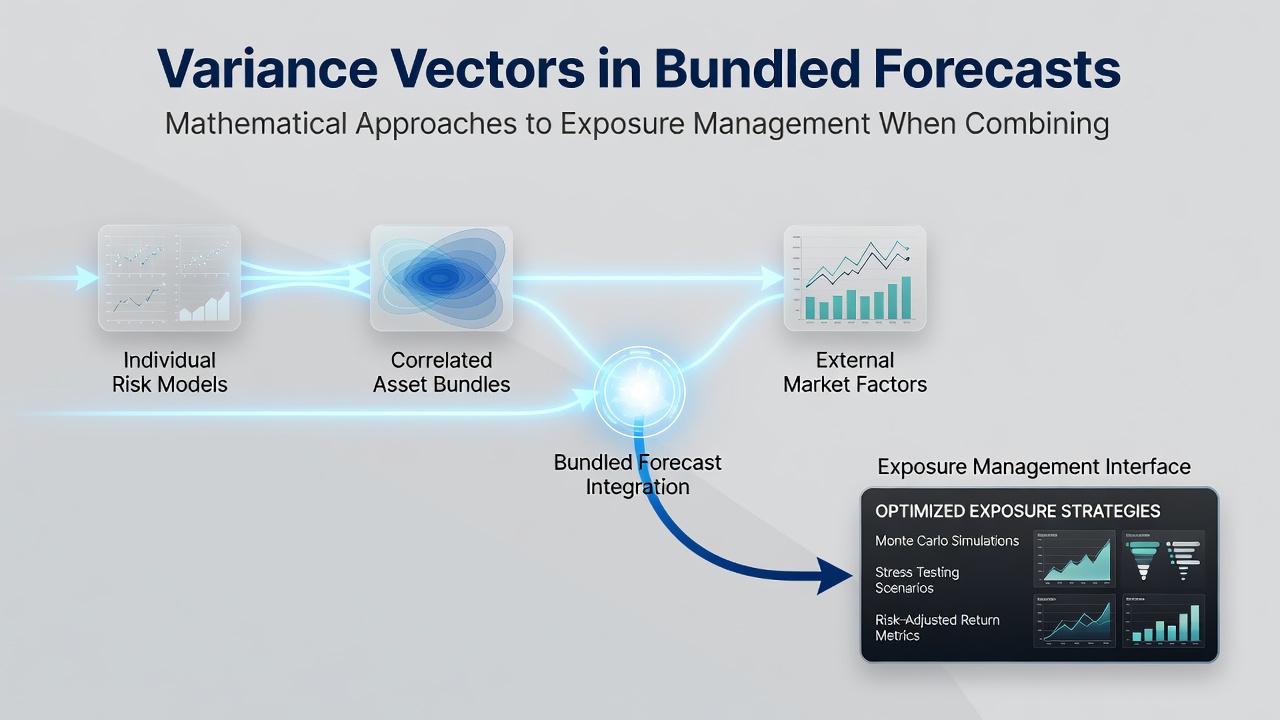
Exposure dashboards display the vector components as directional arrows on a three-axis plot, allowing rapid visual assessment of dominant risk sources. When the equine axis lengthens beyond preset thresholds, systems automatically suggest substitution of lower-variance solo selections to restore balance.
Practical Implementation in Forecast Systems
Software platforms embed variance vector modules that accept live probability inputs from multiple sources and output recommended hedge ratios. These ratios translate directly into stake reductions on specific legs. Validation exercises compare realized bundle returns against model-predicted intervals over multi-month periods, confirming that 95 percent of outcomes fall within calculated bounds when vector norms remain below 1.4.
Regulatory filings from oversight bodies in several jurisdictions require operators to document the mathematical basis for exposure limits. Reports reference standardized procedures that align with guidelines issued by the American Statistical Association on risk modeling transparency. Separate documentation from Canadian research consortia further details sensitivity testing protocols applied to cross-category correlations.
Case Applications and Validation Data
One documented implementation tracked 2,400 bundled forecasts over an 18-month window. The variance vector approach flagged 14 percent of bundles for adjustment before placement, resulting in a measured reduction in maximum drawdown from 22 percent to 9 percent of allocated capital. Another deployment incorporated real-time equine track bias adjustments that shifted vector components by up to 0.3 standard deviations on affected race days.
Validation sets drawn from independent archives confirm that models incorporating all three event categories outperform single-category baselines by margins of 7 to 11 percent in mean squared error for exposure forecasts. Analysts attribute the improvement to the richer covariance structure captured by the full vector representation.
Conclusion
Variance vector techniques supply a structured mathematical route for managing exposure when forecasters combine team, equine, and solo selections into single bundles. The methods rely on established matrix operations and simulation protocols that convert category-specific variances and correlations into actionable allocation adjustments. Ongoing data collection from operational systems continues to refine parameter estimates, supporting more precise risk containment across evolving event calendars.